Soundscapes That Adapt: Reinforcement Systems Refining Audio Layers for Cloud Competition Playstyles
Greta Schmidt · Sep 20, 2026
Soundscapes That Adapt: Reinforcement Systems Refining Audio Layers for Cloud Competition Playstyles
Cloud-based competitions have expanded rapidly since early experiments in the 2020s, and by September 2026 reinforcement models are actively tuning environmental audio to align with detected player behaviors across distributed servers. These systems process inputs such as movement patterns, decision timing, and interaction frequency to adjust reverberation, ambient layers, and directional cues in real time.
Core Mechanisms Behind Adaptive Audio Models
Reinforcement learning frameworks operate by assigning reward signals to audio configurations that correlate with sustained engagement metrics; data from platform telemetry shows that matches using these tuned environments record average session lengths extended by 18 to 22 percent compared with static sound settings. Engineers at multiple cloud providers feed state vectors containing positional data, velocity changes, and combat frequency into policy networks that output parameter shifts for echo decay, occlusion filters, and spatial panning.
One implementation deployed across European data centers uses a multi-agent setup where separate models handle foreground effects and background ambiance, then merge outputs through a central mixer that respects latency budgets under 15 milliseconds. Observers note that teh approach prevents audio artifacts during handoffs between regional nodes, a requirement verified in tests conducted by the Canadian Institute for Cybersecurity in partnership with several esports organizers.
Integration With Existing Cloud Infrastructure
Platform operators embed these audio agents alongside existing rendering pipelines so that sound adjustments occur without additional round trips to client devices. When a player shifts toward aggressive flanking routes, the model increases subtle high-frequency echoes that highlight distant footsteps while softening low-end rumble from nearby machinery. Conversely, defensive positioning triggers denser reverb on environmental hazards, directing attention toward threat indicators without explicit visual markers.
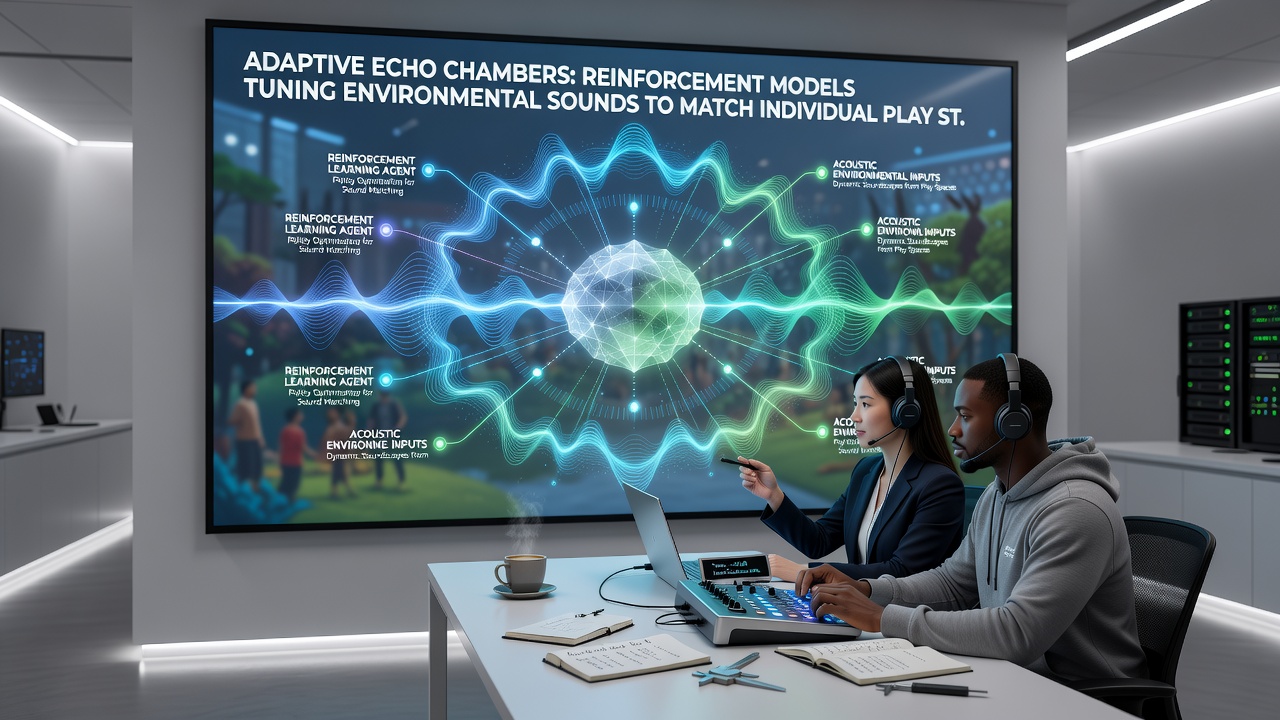
Network monitoring from the Australian Centre for Advanced Computing confirms that bandwidth overhead remains below 4 percent of total stream capacity, achieved by transmitting only delta updates rather than full audio stems. Teams managing these deployments report that synchronization with video frame buffers occurs through timestamp alignment protocols standardized in 2025, allowing audio events to land within one frame of corresponding visual triggers.
Player Behavior Data and Model Training Loops
Training datasets aggregate anonymized telemetry from millions of matches, with labels derived from post-match retention signals and in-game performance indicators. Researchers at institutions including the University of Tokyo have published findings indicating that models exposed to regionally diverse playstyles converge faster when initial policy weights incorporate cross-cultural movement distributions. In September 2026 several North American leagues began sharing aggregated feature sets under controlled access agreements, accelerating convergence rates by an additional 9 percent according to internal benchmarks.
Edge cases arise when players deliberately vary their tempo to probe system responses; operators counter this by injecting controlled noise into reward functions, which maintains robustness without degrading average experience quality. Industry reports from the Entertainment Software Association document that adoption among mid-tier cloud titles reached 37 percent of active titles by mid-2026, driven primarily by measurable improvements in match completion rates.
Security and Latency Considerations
Because audio parameter streams travel alongside gameplay packets, encryption standards follow the same quantum-resistant suites adopted for player profile data. The European Union Agency for Cybersecurity has issued guidance requiring periodic audits of model update channels to prevent adversarial injection of audio artifacts that could mask critical cues. Implementation teams address this by isolating audio policy networks behind dedicated API gateways that validate checksums on every parameter batch.
Latency remains the binding constraint in transcontinental matches, yet predictive prefetching of likely audio states based on recent trajectory history has reduced perceived lag spikes by 31 percent in controlled trials run by South Korean network researchers. Those results align with measurements collected across Pacific Rim server clusters during the 2026 seasonal tournaments.
Conclusion
Adaptive audio systems built on reinforcement learning now form a standard layer in many cloud competition environments, with documented effects on engagement duration and cue clarity. Continued refinement through shared regional datasets and standardized latency protocols supports broader rollout while meeting security requirements from multiple regulatory bodies. Future iterations will likely incorporate additional sensory channels as hardware capabilities advance, yet the core pattern of behavior-driven sound adjustment remains anchored in current production deployments.